Context Efficiency & Prompt Caching
MemoRizz assembles every agent turn to be prompt-cache friendly and deduplicated, so multi-turn conversations and tool loops are billed at each provider's cached-input rate instead of full price, and the model never pays twice for the same memory.
The prompt layout
Prompt caching (OpenAI and Anthropic alike) is a byte-exact prefix match: the first changed byte invalidates the cache for everything after it. MemoRizz therefore orders every request stable-prefix → volatile-tail:
┌─────────────────────────────────────────────────────────────┐
│ tools           sorted; disclosed tools stay visible        │  stable
│ system prompt   frozen for the session                      │  prefix
│ history         append-only, chunk-evicted                  │  (cached)
├─────────────────────────────────────────────────────────────┤
│ final user message                                          │  volatile
│   <memorizz:context>                                        │  tail
│     retrieved memories (deduplicated)                       │  (never
│     entity memory facts                                     │  cached,
│     tool-log digest                                         │  never
│     per-call request context                                │  breaks
│   </memorizz:context>                                       │  the
│   the user's query                                          │  prefix)
└─────────────────────────────────────────────────────────────┘
Everything that changes per turn — retrieved memories, entity facts, the
tool-log digest, the M2 context={...} request payload — is rendered into
the final user message, where it can't invalidate the cached prefix.
The volatile block is never persisted to conversation_memory; only the raw
query is recorded.
Append-only history with chunked eviction
Instead of recomputing a token-fitted history window every turn (which moves the window start every turn and breaks the prefix), MemoRizz evicts history in chunks of 20 messages: the window start stays byte-stable for many turns, then jumps a whole chunk at once — one cache miss per chunk instead of one per turn.
A stable tool surface
Tool schemas are the first bytes of the cached prefix, so any change to the
exposed tool list rewrites everything after it. Progressive disclosure picks
the most relevant tools for each query, which would change the list almost
every turn. Tools already disclosed to an agent's user therefore stay
visible (and callable), up to ContextPolicy.sticky_tool_limit (default 15);
past the bound the least recently selected tool is evicted. The list changes
only when a genuinely new tool is needed, and the converged surface is shared
by every conversation with the agent. Set sticky_tool_limit=0 to re-select
every turn.
Even sticky tools change the list whenever a new one first becomes relevant,
and each change re-writes the whole cached prompt, history included. So when
all of an agent's tool schemas fit in ContextPolicy.stable_tool_list_tokens
(default 6,000 tokens), every tool is sent on every turn instead and the list
never changes. Only larger catalogs, such as agents with many MCP tools, use
progressive disclosure. Set stable_tool_list_tokens=0 to always disclose
progressively.
tool_top_k does nothing for small catalogs
While every tool schema fits in stable_tool_list_tokens, the agent sees
all of its tools on every turn, so tool_top_k and sticky_tool_limit
have no effect. That default is deliberate: a list that never changes
keeps the provider prompt cache intact. To make tool_top_k limit the
tools sent, lower stable_tool_list_tokens (or set it to 0).
One tool list per turn
A streamed turn makes a private tool-phase call, then generates the public answer in a further call. That answer call sends the same tool list as the tool phase, so it extends the turn's cached prefix instead of starting a separate cache chain that would re-bill the whole history every turn. The host keeps the answer tool-free: a tool call made while answering is never run.
History is loaded per thread. Streaming callers that continue a conversation
should pass its thread_id; a run without one starts a new thread and sees
no earlier turns. The UI playground continues the selected memory's most
recent thread, as the CLI does.
Provider support
Anthropic
The Anthropic LLM provider attaches cache_control breakpoints
automatically (enable_prompt_caching=True by default):
- on the system prompt — caches tool schemas + system text for every
tool-loop iteration and follow-up turn. Reviewed developer-authority skills
ride in a separate block after this breakpoint, so a skill change does not
invalidate the cached tools and system prompt;
host notes added during a turn (for example "evidence collection is
complete") are appended to the user turn they follow, inside
<system-reminder>tags, rather than to the system prompt, which stays byte-identical across every call; - on the final message — the read point for the next iteration of the same turn's tool loop;
- on the second-to-last message — the cross-turn read point that lets the growing conversation accrue incremental cache hits.
Request construction is isolated from MemAgent's reusable history: MemoRizz annotates provider-owned deep copies, so cache metadata cannot leak into a later tool-loop iteration. It also enforces Anthropic's request-wide maximum of four breakpoints across tools, system content, and messages. Existing caller-supplied breakpoints are preserved and consume the budget before MemoRizz adds its own; an already-invalid request containing more than four fails locally before an API call.
Single-shot generate_text calls (summaries, extraction, Evalground readers
and judges) cache only the instructions: nothing extends their unique prompt,
so a message breakpoint would only add the 1.25× write premium. Exact-repeat
workloads (for example repeated evaluation runs) therefore do not reuse the
prompt body on Claude.
Reads bill at ~0.1× input price; disable with
Anthropic(..., enable_prompt_caching=False).
Measured on a six-turn conversation with two tool calls (Claude Sonnet 5):
93% of input tokens were cache reads, and each turn wrote only what it added
(about 50–460 tokens). The same conversation on gpt-4.1-mini reused 84% of
its input tokens.
OpenAI
OpenAI caches automatically for prompts ≥ 1024 tokens, keyed on the exact prefix. MemoRizz maximizes hits by:
- pinning a
prompt_cache_keyper conversation (memorizz:{agent_id}:{memory_id}), so requests route to the same cache shard. Callers that set no key (single-shot helpers, Evalground readers and judges) get one derived from the model and their instructions: in live tests, Responses requests without a key did not reuse a shared prefix; - optional
prompt_cache_retention="24h"(OpenAI(..., prompt_cache_retention="24h")) for long-lived agents on models that support extended retention.
Models before GPT-5.6 cache any previously seen prefix, so MemoRizz adds no
annotations for them. GPT-5.6 and GPT-6 write implicitly only at the latest
message (which carries the per-turn volatile block) and read only from
explicit prompt_cache_breakpoint blocks on input content; breakpoints on
assistant output are not used for reads. On both Chat Completions and
Responses, MemoRizz marks provider-owned copies at two input boundaries:
- the end of the leading system/developer instructions;
- the last user message before the final one — stable history that the next turn's breakpoint finds by lookback.
Without the history boundary each turn re-writes the whole conversation; in a
live probe with ~5k tokens of history it raised the next turn's cache read
from 2.6k to 7.7k tokens. Caller-supplied breakpoints are left as they are.
prompt_cache_retention is the legacy control for models before GPT-5.6;
newer model families use prompt_cache_options.ttl.
Cache parameters are only sent to the official endpoint — local OpenAI-compatible servers (llama.cpp, LM Studio, vLLM) are left untouched.
Verifying cache hits
Where to look:
- Agent playground — the Prompt Cache card shows the agent's cache read rate (cached share of input tokens) and hit rate (calls that read from the cache), plus the last turn's calls, reads and writes. Details opens the usage page filtered to the agent.
- Observability → Usage — the same rates, cached and written tokens, a per-model breakdown and cache-drop warnings for any filter.
- Evalground — memory-suite results show a provider prompt-cache panel and per-lane cache writes and hit rates; Compare models & rerankers adds a cache hit-rate column per call lane.
- Code —
agent.get_last_run_usage()sums every model call of the last run (tool-loop iterations included), and the streamingrun.doneevent carries the same summary asusage. The native MetaHarness adapter reports these whole-run totals, so its input and output token budgets apply.
agent.model.get_last_usage() surfaces the last call's cache metrics on both
providers:
agent.run("first turn")
agent.run("second turn")
print(agent.model.get_last_usage())
# {'prompt_tokens': 7844, 'completion_tokens': 20, 'total_tokens': 7864,
#  'cached_tokens': 7748, 'cache_read_input_tokens': 7748}
If cached_tokens stays 0 across turns, something is mutating your prefix —
the usual suspects are a per-turn timestamp in a custom instruction or a
tool set that changes between requests.
Pre-inference deduplication
Everything retrieved for a turn (episodic recall, knowledge-base chunks)
passes through a dedup/selection pipeline
(memorizz.memagent.utils.context_dedup) before it reaches the context
window:
- Exact dedup — normalized-content fingerprints across all sources.
- History dedup — anything already present (verbatim or contained) in the conversation window going into this prompt is dropped.
- Near-dup dedup — cosine similarity ≥ 0.95 between stored embeddings (vectors come back with the rows, so this costs no extra embedding calls).
- MMR selection — maximal marginal relevance (relevance blended with recency decay) picks a small, diverse subset.
- Character budget — each memory is cut to
RetrievalPolicy.max_chars_per_itemcharacters (600 by default). Withmax_recall_charsset, the selected memories share that total, and the most relevant memory gets its text first. See how much text each memory keeps. - Stable ordering — selected memories render oldest-first with deterministic tie-breaks, so the block doesn't reshuffle between turns.
Write-path guards complement it: identical consecutive (query, response)
pairs (semantic-cache hits, client retries) are not double-written, and
entity upserts that add no new information skip the re-embed and re-store
entirely.
Choose automatic retrieval explicitly
Memory types describe what an agent can store and expose through tools.
RetrievalPolicy independently controls what semantic matches are injected
before inference:
from memorizz import MemAgent, MemoryType, RetrievalPolicy

agent = MemAgent(
    memory_provider=provider,
    memory_types=[MemoryType.CONVERSATION_MEMORY, MemoryType.KNOWLEDGE_BASE],
    retrieval_policy=RetrievalPolicy(
        conversation_scope="thread",
        knowledge_base_scope="namespace",
        knowledge_base_namespaces=("agent-harness",),
    ),
)
Use RetrievalPolicy.disabled() when the application already has explicit,
tenant-scoped search tools. Exact current-thread history still loads normally;
only automatic semantic recall is disabled.
The scopes:
| Field | Values | Default |
|---|---|---|
conversation_scope |
memory (every thread of the memory), thread, disabled |
memory |
knowledge_base_scope |
memory (the attached knowledge bases), namespace (only knowledge_base_namespaces), disabled |
memory |
entity_scope |
memory (facts shared by the memory's threads), thread (a thread's facts stay in it, both written and recalled), disabled (not recalled automatically; the entity tools still work) |
memory |
workflow_scope |
memory (past workflows from every thread of the memory and user), thread (this thread's only), disabled |
disabled |
A string works too:
"thread"narrows conversation recall and leaves the knowledge base on. It used to turn the knowledge base off as well, and agents saved with"thread"before the fix still haveknowledge_base_scope="disabled"stored: set it back to"memory"if they should recall it."sealed"isRetrievalPolicy.sealed(). See sealed threads."memory","namespace"and"disabled"are the other shortcuts.
The learning control plane's evidence pack follows the same policy.
Search only the memory a request needs
RetrievalPolicy(read_routing=True) asks a decision model, before recall,
whether the request needs episodic, semantic or procedural memory, and skips
the stores it doesn't need: "What's 2 + 2?" searches nothing. See
Decision Models.
Recall past workflows
An agent with workflow memory stores each turn that calls tools: the request,
each tool call with its arguments and result, and the outcome. With
workflow_scope set, recall offers those workflows alongside the other
memories, one line each:
agent = MemAgent(
    ...,
    memory_types=[MemoryType.CONVERSATION_MEMORY, MemoryType.WORKFLOW_MEMORY],
    retrieval_policy=RetrievalPolicy(workflow_scope="memory"),
)
• [workflow 2026-11-05; id=…] Earlier task "Will it rain in Lisbon during my
  trip?": weather_outlook({"place": "Lisbon", …}) worked;
  exchange_rate({"base": "GBP", …}) failed: ECB feed timed out. Outcome: failure.
Tool results are left out, because they can be long and go stale. A workflow
that a learned skill covers isn't recalled, since the skill is shown instead.
Workflows stay with the memory and user they ran for. With a thread-scoped or
sealed policy, recall uses only the current thread's workflows, and a sealed
thread's workflows are never recalled in another thread. They compete for
max_items with the other memories.
How much text each memory keeps
Each recalled memory is cut to 600 characters by default. Long assistant answers can lose the detail a later question asks about. Two fields change this:
| Field | What it does | Default |
|---|---|---|
max_chars_per_item |
Characters kept per recalled memory. None keeps each memory whole. |
600 |
max_recall_chars |
Characters of recalled text per turn, across all memories. None sets no total cap. |
None |
When you raise or remove the per-item cap, set a total cap too, so a few long memories cannot flood the prompt:
Under a total cap the most relevant memory gets its text first. A memory
that does not fit whole is cut to the room left, or left out when little
room is left. The block still renders oldest-first, so it stays
prompt-cache friendly. A cut memory has truncated: True in
agent.last_retrieval_evidence()["items"]. Both fields are saved with the
agent, and the defaults keep existing agents as they were.
A policy for one call
run(), run_stream() and run_stream_events() take retrieval_policy=
for that call only. A scope string such as "sealed" or "thread" changes
just those scopes and keeps the agent's other settings (scoring, retention,
namespaces). A RetrievalPolicy or a dict replaces the agent's policy for
the call.
The agent's own policy, and what save() writes, stay as they are. Calls
running at the same time on a shared agent each keep their own policy.
Delegates use their own policies.
What was recalled, by source
The memory_context trace (stage supplied) counts what reached the prompt,
and the playground shows it per turn under Memory supplied, for example
"3 recalled memories (2 from the knowledge base, 1 from conversations)".
source_counts["semantic_memories"] is every semantic match.
semantic_source_counts splits it into knowledge_base and conversation.
evidence_source_counts does the same for evidence-pack items.
Retrieved record ids for evaluation
semantic_refs, entity_refs and evidence_refs hold SHA-256 fingerprints,
not record ids. A retrieval evaluation (for example recall@k against
LongMemEval's answer sessions) needs the plain ids. Ask for them:
agent.run(question, memory_id=memory_id, thread_id=thread_id)
evidence = agent.last_memory_context_evidence(include_ids=True)
for item in evidence["retrieved"]:
    print(item["memory_type"], item["record_id"], item["thread_id"], item["score"])
Each retrieved entry has:
ref: the fingerprint it explains, so it joins tosemantic_refs,entity_refsorevidence_refs;memory_type: for exampleconversation_memoryorknowledge_base;record_id: the stored record's id;thread_id: the conversation the record came from (Nonefor knowledge base chunks);score: the selection score;source_idandtruncatedwhen they apply.
The ids are opt-in. Without include_ids=True the method returns what it
always did. They never go into traces, the UI or the default snapshot, and
each concurrent call on a shared agent sees only its own turn's ids. Only
code that holds the agent object can read them.
agent.describe_memory() returns:
- the agent's active memory types;
- whether entity memory is on;
- the memory tools the model can call;
- the retrieval policy;
- the background model;
- the consolidation schedule.
The agent also logs this at INFO when it is built, for example: "remembers
conversation_memory, knowledge_base, …; entity facts on, shared across
threads; memory tools: entity_memory_lookup, …". Assistant mode turns entity
memory on. with_entity_memory(False), or memory_types without
entity_memory, turns it off.
While a user has no entities, entity_memory_lookup is left out of the turn's
tools and the prompt does not ask for it. In an evaluation, an unneeded lookup
roughly doubled a turn's input tokens and added about ten seconds. The check
is one small scoped query, cached per memory and user. The per-turn entity
recall usually answers it first, so it rarely costs a query of its own.
entity_memory_upsert is always offered, and the lookup comes back on the
turn after the first entity is written.
Semantic response caching is session-scoped by default. Its fingerprint also includes per-request context, so the same query on a different page or quoted selection is a miss rather than a stale replay.
Tool call cache
A MemAgent with a tool cache answers a repeated tool call (the same tool, the same arguments, for the same user) from a stored result instead of running the tool again, while that result is fresh. It saves the tool's latency, and any cost or rate limit behind it; the model's work is unchanged.
from memorizz import MemAgentBuilder, governed_tool


@governed_tool(cacheable=True, cache_ttl_seconds=600, domains=("orders",))
def lookup_order(order_id: str) -> dict:
    """Look up an order's status, carrier and dates."""
    return orders_api.get(order_id)


agent = (
    MemAgentBuilder()
    .with_llm_config({"provider": "openai", "model": "gpt-4.1-mini"})
    .with_tools([lookup_order])
    .with_tool_cache()  # or MemAgent(..., tool_cache=True)
    .build()
)
Turn it on with tool_cache=True (or a ToolCacheConfig/dict),
.with_tool_cache(), memorizz agents create --tool-cache, or Enable tool
call cache on the agent form in the UI. The setting is saved with the agent.
What may be cached. Only calls that are safe to reuse:
- Python tools that opt in with
@governed_tool(cacheable=True). A cacheable tool must be deterministic, have no side effects and not need approval; anything else is rejected when the tool is defined. - MCP tools whose server marks them read-only (
readOnlyHint) and idempotent (idempotentHint). A read-only tool that isn't idempotent (live tracking, a stock price) always runs.ToolCacheConfig(mcp="off")never caches MCP results.
Every other tool, every failed or degraded result, and every call that needs approval runs as before.
How long. A result lives for the tool's cache_ttl_seconds, else the
cache's ttl_seconds (300 by default), and never longer than the freshness of
a domain the tool declares (freshness_by_domain: MCP results 300 s,
inventory and calendar 60 s).
For whom. A key covers the tool and its arguments (in any order), the user,
and a fingerprint of the tool: its code and schema, or its MCP server. A
changed tool therefore never returns an old result, and one user never sees
another's. With scope="agent" (the default) entries also belong to one agent;
scope="user" shares them between agents serving the same user.
Results are kept in a process-wide LRU, so every run of the agent in one
process shares them: the local UI and its harness runs, a REPL session or a
worker. Hits and misses appear on the tool's trace event
(cache: {"status": "hit", "age_seconds": ..., "saved_ms": ...}, where
saved_ms is how long the call took when its result was stored), in
agent.tool_cache_stats(), and in the UI: a trajectory step reads "from
cache", and the harness Compare view counts the calls each run took from
the cache.
agent.tool_cache_stats()        # hits, misses, stored, bypasses (with reasons), saved_ms
agent.invalidate_tool_cache("lookup_order", user_id="ada")  # after the data changes
Within one turn the tool router already refuses an identical repeat call, so the cache pays off across turns and runs: the same order looked up for a later ticket, the same quote asked for twice.
Measured. A support agent (local qwen2.5:7b) worked a queue of eight
tickets, each in its own conversation, against an order API that takes 1.5 s
and a shipping-quote API that takes 1.0 s
(examples/tool_cache):
| Per queue (two rounds, averaged) | No cache | Tool cache |
|---|---|---|
| Real API calls | 8 | 4 |
| Tool time saved | — | 5.5 s |
| Queue time | 36.6 s | 28.6 s |
| Correct answers | 8 of 8 | 8 of 8 |
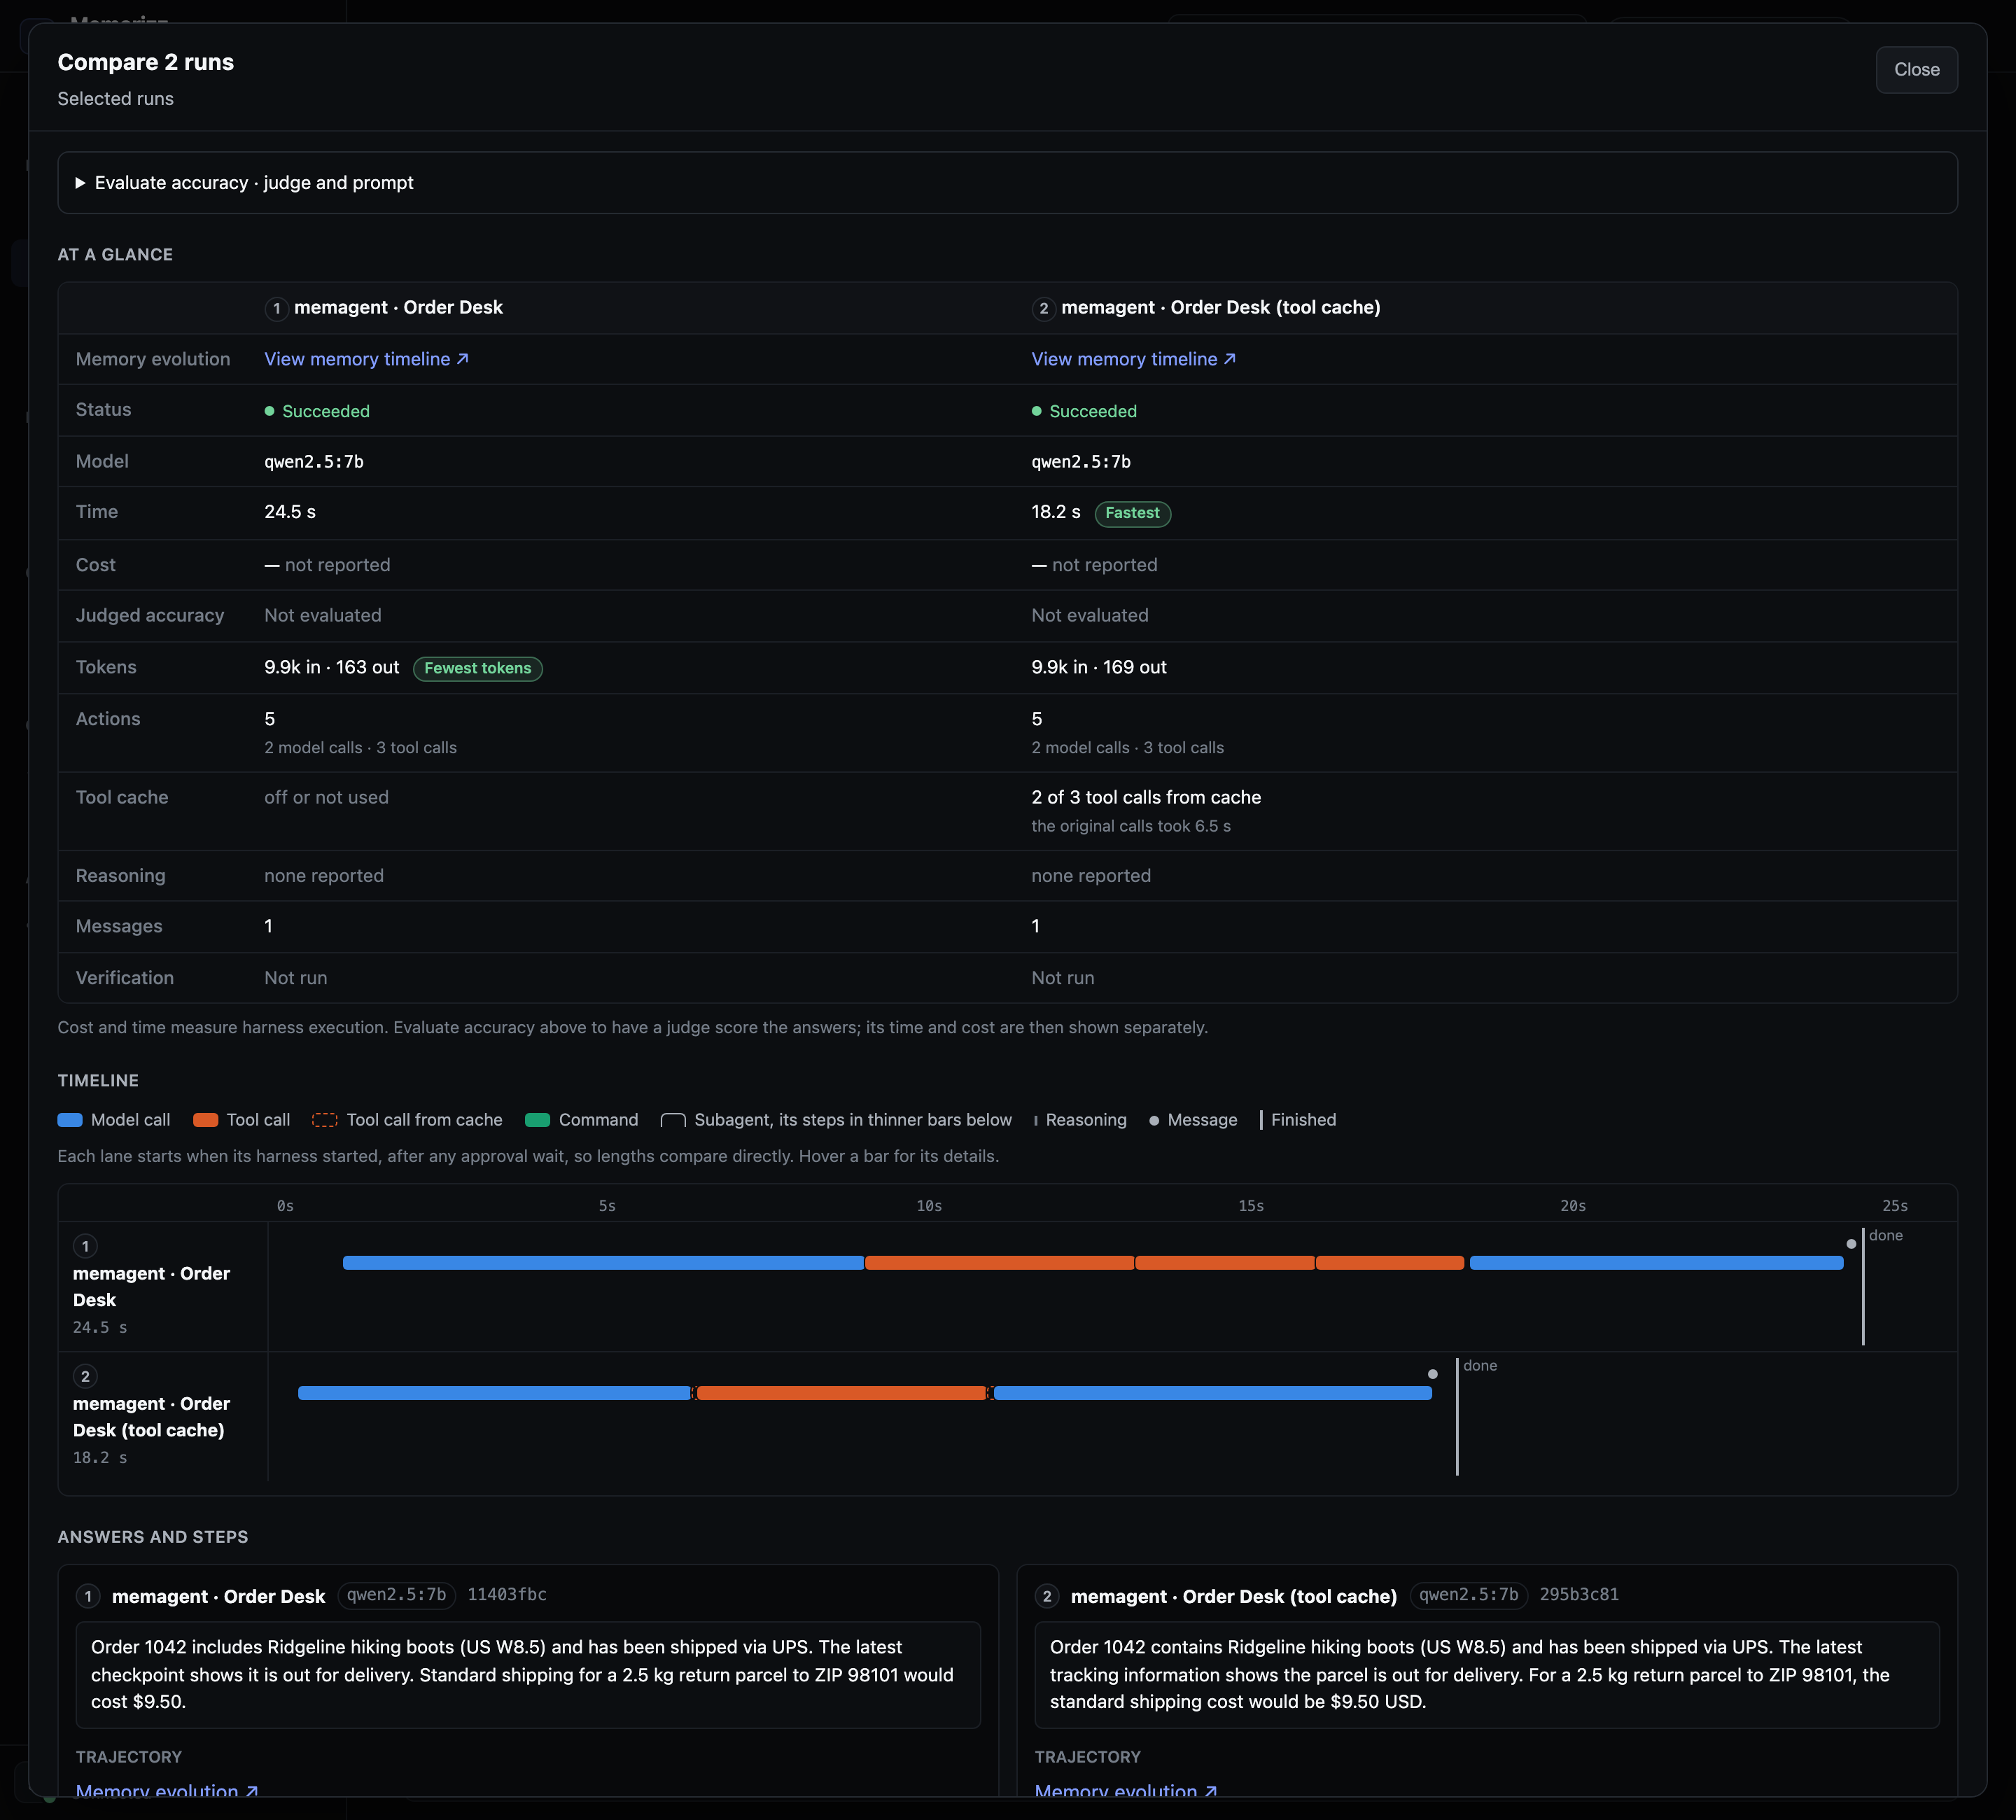
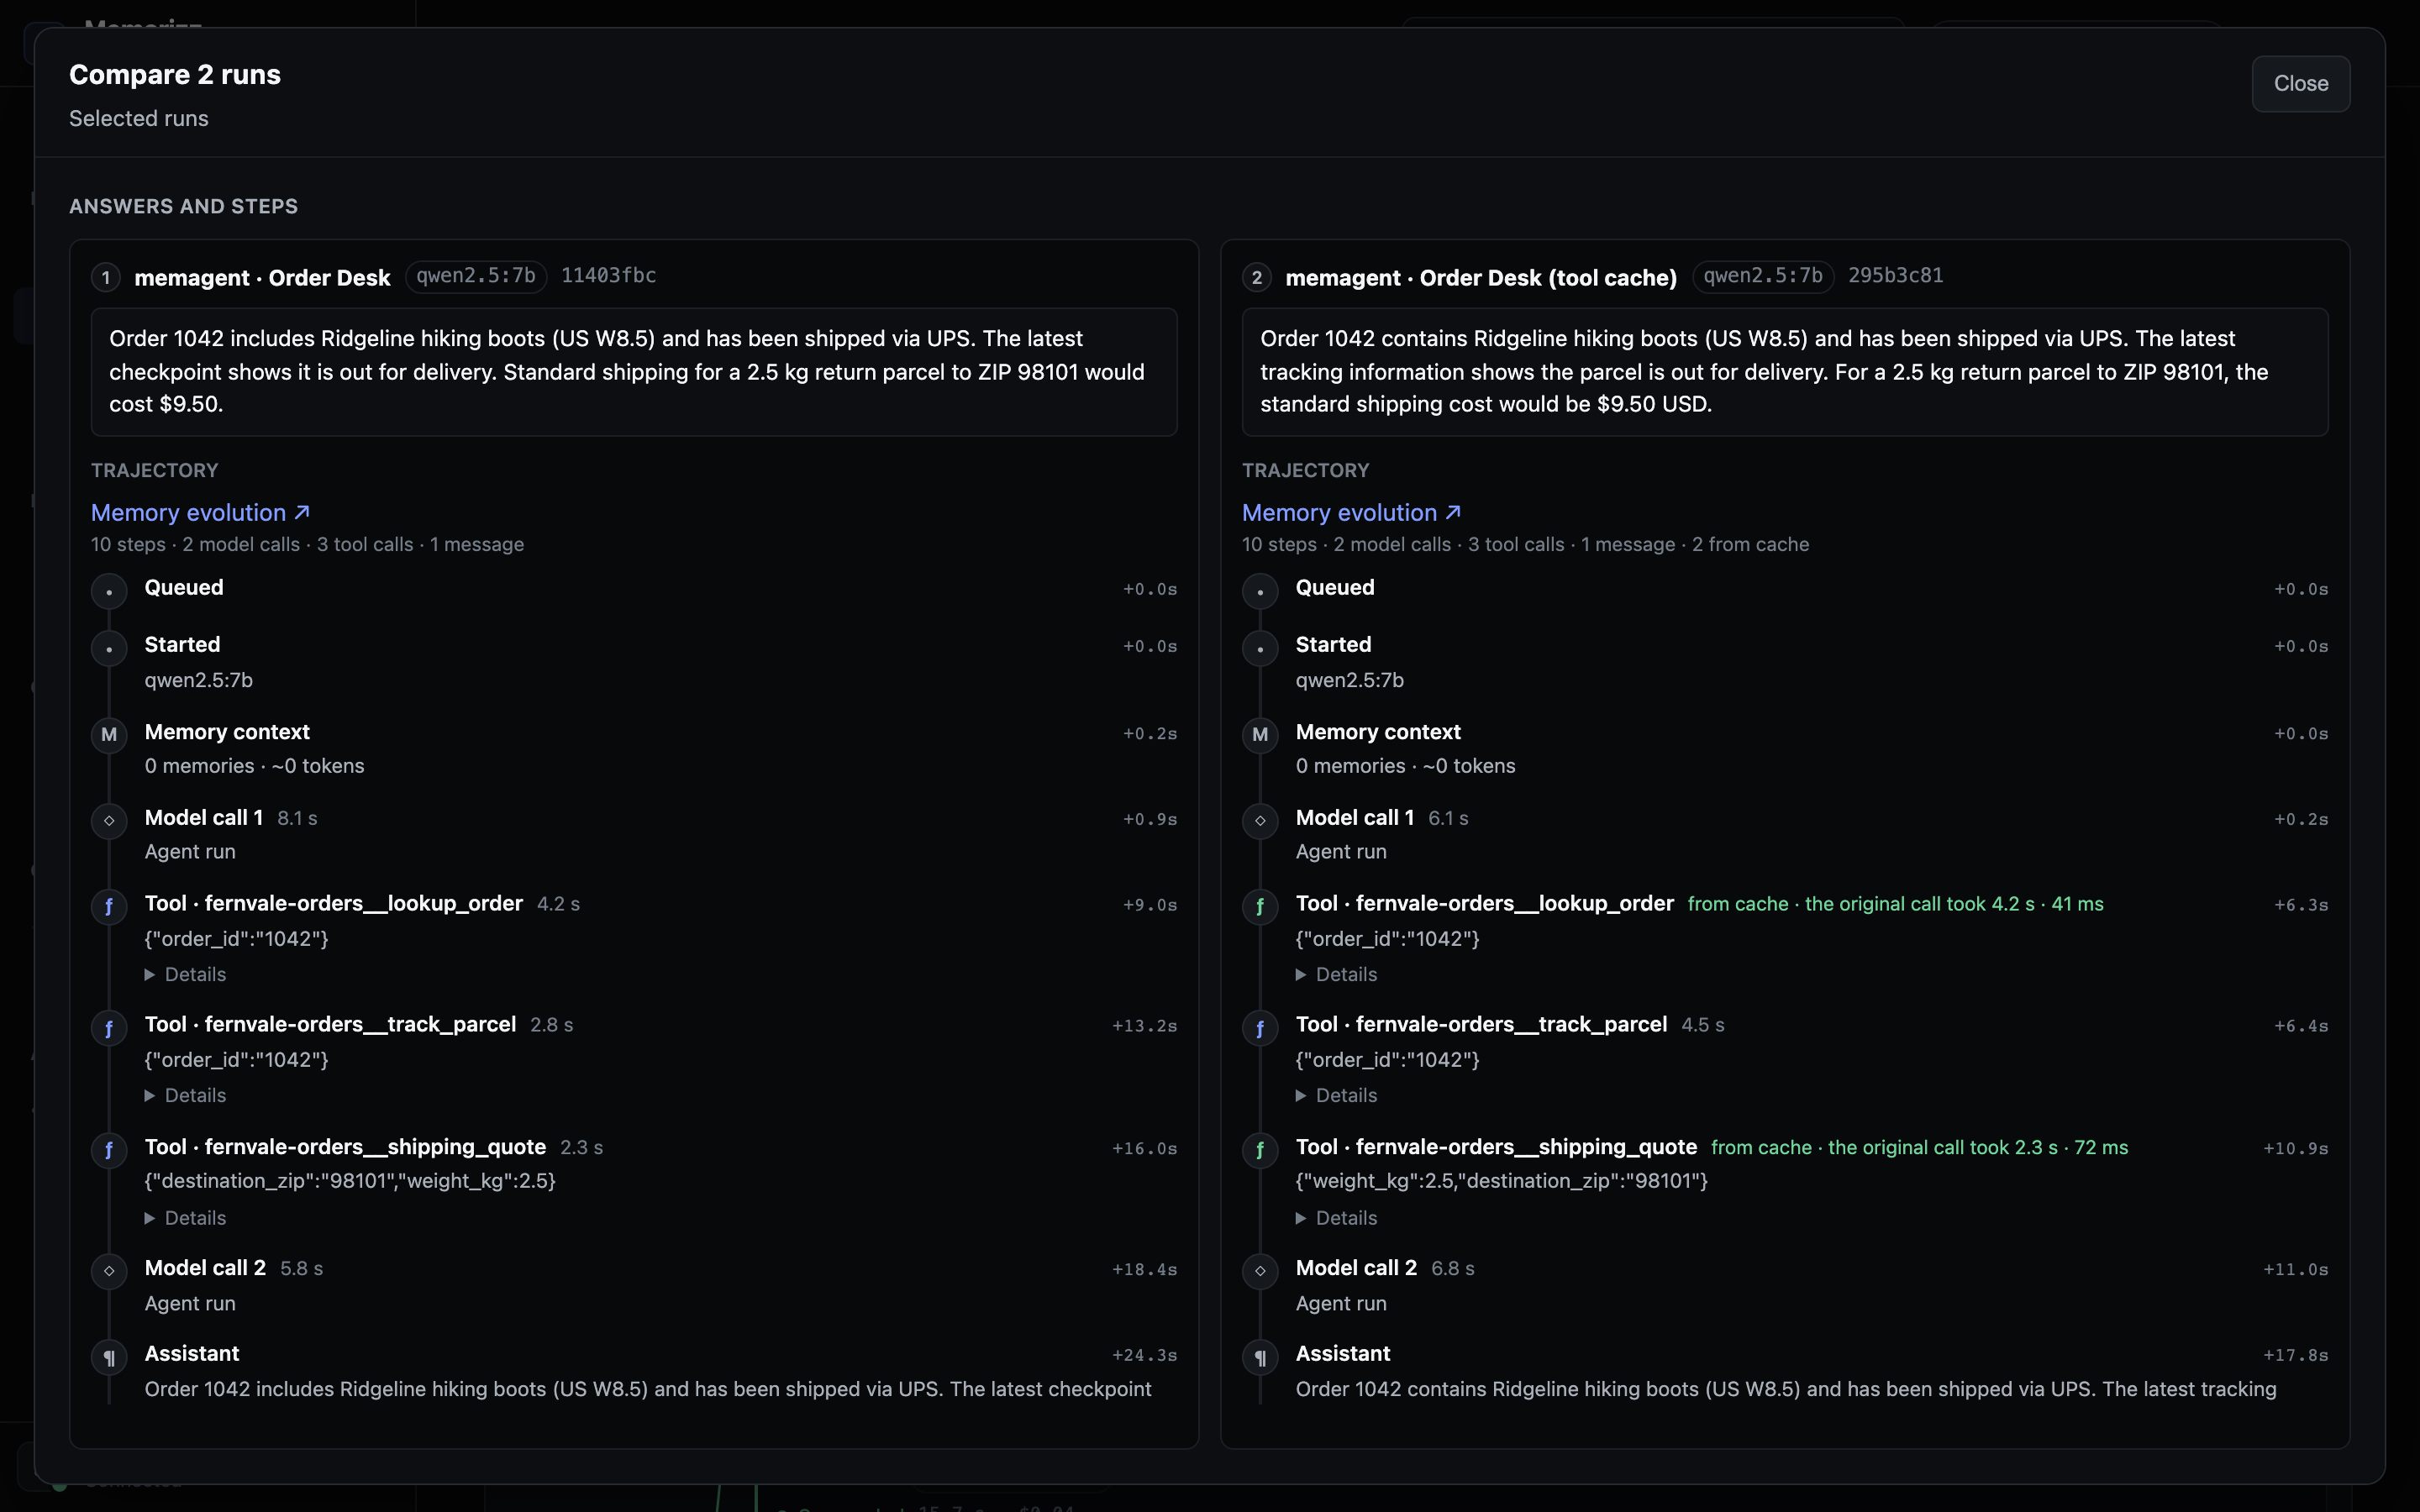
The side-effecting tool in the queue (creating a return label) ran every time. In the UI, two otherwise identical agents on the same MCP task took 24.5 s and 18.2 s: the order lookup and shipping quote came from the cache in under 0.1 s, while live parcel tracking ran in both.
Fewer embedding calls
EmbeddingManagermemoizes text → vector (LRU): the same query used by the semantic cache, episodic recall, KB recall, and entity search within one turn is embedded once.- Conversation rows are written with
embedding=Noneand backfilled by a single background worker, so the user-facing turn never blocks on the embedding API. Disable withMEMORIZZ_DISABLE_CONVERSATION_EMBEDDINGS=1.
Auto-compaction
Every request is capped at 80% of the model's context window, leaving room for the answer. Without compaction, the oldest messages that don't fit are simply left out. Auto-compaction summarizes them first, so the model keeps the gist:
- Before building a request, the agent estimates it with the thread's full,
unsummarized history (system prompt, tool schemas, query and history). At
or above
context_policy.compact_atpercent of the window (default 80), it summarizes the older messages into summary memory and keeps the newestkeep_recent_messages(default 6) word for word. - The summary text goes into the prompt ("Earlier in this conversation"),
and the compacted messages stop being sent. Stream events report it:
a
statuswithstage="compacting_context", thencontext.compactedwith the message count and the token estimate before and after. - It compacts in batches of at least
keep_recent_messagesolder messages, so a threshold below the size of the prompt without history does not trigger a summary on every turn. - It needs summary memory;
compact_at=0turns it off. Valid thresholds are 30–80.
In the playground, Overview → Context window has an Auto-compact at selector that saves the threshold on the agent (and turns on summary memory when needed). The panel estimates the next request the way the agent builds it: trace records shown in the thread and summarized messages are not counted, and after each turn it shows the measured size of the last request. Compact context summarizes the older messages now, with the same rules.